Statistical Analysis for Football Betting: Data-Driven Strategies
 Available in US
Statistics in football betting are simultaneously overrated and underutilized, which sounds contradictory until you understand what I mean. They're overrated because people think plugging numbers into spreadsheets automatically generates winning bets. They're underutilized because most bettors either ignore data completely or use basic surface statistics that tell you almost nothing useful about future match outcomes.
The transformation in football analytics over the past decade has been remarkable. Ten years ago, betting decisions relied primarily on watching matches, reading match reports, and tracking basic stats like goals scored and league position. Now we have expected goals, progressive passing metrics, pressing intensity data, and dozens of other measurements that reveal what's actually happening on the pitch versus what scorelines suggest.
But here's what nobody tells you---having access to advanced statistics doesn't automatically make you profitable bettor. Most people drown in data, unable to separate signal from noise, or they cherry-pick stats that support bets they've already decided to make emotionally. The skill isn't accessing statistics. The skill is knowing which statistics actually matter, how to interpret them properly, and how to convert analytical insights into betting edges before markets correct.
I've spent years building statistical models, testing which metrics predict future performance versus which just describe past results, and learning the hard way that statistical significance and betting significance are completely different concepts. A correlation that's statistically valid might be completely useless for betting if bookmakers already price it accurately.
This guide breaks down which football statistics genuinely matter for betting, where to find reliable data, how to avoid common analytical mistakes that lose money, and most importantly, how to identify statistical inefficiencies that bookmakers haven't fully incorporated into their odds. We're going beyond "team A averages 2 goals per game" toward understanding why those goals happen and whether that rate will continue.
Essential Football Betting Statistics
Expected goals changed everything. Seriously, if you're betting football in 2025 without understanding xG, you're operating with one hand tied behind your back. Expected goals measures shot quality by assigning probability to each shot based on location, assist type, defensive pressure, and other factors. A shot from six yards out might have 0.75 xG---meaning similar shots score 75% of the time historically. A speculative effort from thirty yards might be 0.03 xG.
Why this matters for betting: actual goals contain massive randomness over small samples. Team might score three goals from three shots in one match through luck or exceptional finishing, then fail to score from fifteen shots the next week. Looking only at scorelines suggests the team got worse. Looking at xG reveals they actually created better chances in the second match and were unlucky not to score.
This creates betting opportunities when teams are overperforming or underperforming their xG. Team consistently scoring more than their xG suggests---like banging in goals from low-quality chances---they're probably due for negative regression. Smart bettors fade these teams, taking unders on their goals or backing their opponents. Conversely, team creating high xG but not converting is frustrating their fans and probably underpriced by bookmakers. These teams offer value because underlying performance predicts future results better than recent scorelines.
Expected goals against (xGA) reveals defensive quality beyond clean sheets and goals conceded. Team might have three clean sheets in five matches, looking solid defensively. But if their xGA during that stretch was 8.5---meaning opponents created 8.5 goals worth of quality chances that didn't convert---they've been lucky, not good. The goals are coming. Build betting strategies around this inevitable regression.
The opposite scenario is equally valuable. Team conceded six goals in three matches, looking defensively terrible. But if their xGA was only 3.2, they've been exceptionally unlucky, probably due to poor goalkeeping or individual errors on high-quality opposition finishing. The defensive performance is actually decent and likely to improve.
Shots on target percentage reveals attacking efficiency that raw shot counts hide. Team taking twenty shots per match sounds impressive until you realize only four are on target. They're generating volume but not quality. Team taking twelve shots with eight on target is more dangerous despite lower total volume. This affects over/under goals markets and team-specific goal totals.
Progressive passing statistics measure passes that advance the ball significantly toward opponent's goal. Total passes and passing accuracy are nearly worthless metrics---you can complete 600 passes in your own half and accomplish nothing. Progressive passes, passes into final third, and passes into penalty area actually correlate with goal creation and offensive effectiveness.
Possession statistics need massive context. Possession percentage alone tells you almost nothing about match quality or betting value. What matters is possession location and quality. Five minutes of possession in opponent's final third creates more danger than fifty minutes of possession in your own half. Expected threat (xT) models quantify possession quality by measuring ball progression toward dangerous areas.
Defensive actions statistics reveal how teams defend beyond just goals conceded. Tackles, interceptions, blocks, and pressures in different zones show whether team defends high up the pitch or sits deep, whether they're aggressive or passive, whether they're organized or chaotic. These characteristics affect match tempo, goal expectation, corner counts, and card accumulation---all things you can bet on.
Set piece efficiency separates teams dramatically in ways that general statistics obscure. Some teams score or concede disproportionately from corners, free kicks, and penalties. If you're betting on team that scores 30% of their goals from set pieces against team that defends set pieces excellently, total goals expectation should adjust downward from what overall scoring rates suggest.
Individual player statistics become crucial for player prop betting. Shots per 90, shots on target percentage, expected goals per 90, expected assists, progressive carries, successful dribbles, tackles, interceptions, fouls committed, fouls drawn---all of these predict player performance in specific markets. If bookmaker offers 2.50 odds on player recording shot on target but that player averages 1.2 shots on target per 90 minutes, suggesting around 70-75% frequency, you've found value the bookmaker mispriced.
Finding and Using Reliable Football Data
Free statistical resources have prolifoded dramatically. Websites like FBref, Understat, and WhoScored provide comprehensive statistics for major leagues at no cost. FBref offers particularly deep analytics including expected goals, progressive passing, defensive actions, and possession metrics---basically everything you need for serious analysis without spending money.
The challenge with free data is that everyone has access to it, which means obvious insights get incorporated into betting markets quickly. If crystal-clear pattern appears in publicly available statistics, bookmakers have seen it too and adjusted odds accordingly. Your edge comes from analyzing the data more deeply, combining it with other information sources, or identifying patterns that exist but aren't obvious to casual observers.
Premium data providers like Opta and StatsBomb offer more granular information, faster updates, and proprietary metrics. Professional bettors and betting syndicates pay for premium data because competitive edges are often small and every informational advantage matters. For casual bettors, free data combined with superior analysis usually provides sufficient edge without the significant expense.
API access for automated data collection separates serious from casual analysis. Manual copying of statistics from websites is time-consuming and error-prone. APIs let you automatically collect data, update databases, and run models without manual intervention. Some free APIs exist---football-data.org for example---while premium providers offer more comprehensive API access.
Database management becomes essential once you're collecting significant data. Store historical statistics, track your betting results, and build dataset for analysis and modeling. Simple solution might be Excel or Google Sheets. More sophisticated approach uses SQL database or Python with pandas for data manipulation. The key is consistency---collect same data regularly so you can track changes over time.
Real-time data versus historical data serves different purposes. Historical data helps identify patterns and build models. Real-time data---lineups, injuries, weather---affects immediate betting decisions. Combine both for comprehensive analysis. Use historical data to identify value bets, then verify with real-time information before placing wagers.
Data quality and reliability varies dramatically across sources. Some websites have errors, outdated information, or inconsistent definitions. Cross-reference important statistics across multiple sources when possible. Build your own tracking to verify external data accuracy over time. One bad data point can ruin analysis or model, so quality control matters.
Understanding data definitions prevents misinterpretation. Different providers might calculate "big chances" or "key passes" differently. Shot might be on target by one definition but not another. Read methodology documentation carefully. When building models or comparing across sources, ensure you're using consistent definitions.
Apply these stats to our bet builder strategy guide.
Common Statistical Mistakes in Football Betting
Small sample size conclusions are the most dangerous mistake. Five matches tell you almost nothing about true team quality. Random variance dominates small samples. Team might win five straight through luck, or lose five straight despite playing well. Need minimum 10-15 matches for patterns to become meaningful, preferably 20-30 for real confidence.
The mathematical reality: even 60% win probability team loses 40% of the time. Over five matches, that team could easily lose three or four just through variance. Concluding they're bad based on this would be completely wrong. Wait for larger samples before drawing conclusions.
Overweighting goals versus underlying metrics causes systematic errors. Goals are what matter for match results, but they're also the noisiest statistic with highest variance. Team scoring four goals might have gotten lucky with deflections and goalkeeper errors. Team scoring zero might have hit the post three times. Expected goals and shot quality metrics predict future performance better than past goals.
Professional approach weights underlying metrics more heavily than results for future predictions. Recent scorelines influence odds because public bettors overreact to them. This creates value opportunities for bettors who look deeper.
Ignoring strength of schedule makes statistics misleading. Team might have excellent statistics because they played weak opponents. Another team might have poor statistics because they faced title contenders repeatedly. Raw numbers without context lead to wrong conclusions.
Always adjust for opponent quality when evaluating statistics. Scoring two goals against Manchester City means something different than scoring two against relegation candidate. Build strength-adjusted metrics or at least mentally adjust for schedule difficulty.
Home/away splits matter more than most bettors realize. Some teams are completely different at home versus away---different tactics, different confidence, different referee treatment. Using combined statistics misses these crucial differences. Always separate home and away performance for analysis.
The variance in splits can be extreme. Team might have 2.0 xG at home but 0.8 xG away. Their defense might be solid at home but leak goals away. Using their average statistics for all matches would misprice both their home and away matches significantly.
Not accounting for injuries and team selection affects statistical relevance. Team's statistics with their first-choice eleven don't apply when key players are injured. Historical data becomes less relevant when personnel changes significantly. Track statistics with and without key players when possible.
Recent transfers particularly affect statistical models. New striker changes attacking patterns. New defender changes defensive structure. Last season's statistics might be completely irrelevant after significant squad changes. Weight recent data more heavily when squads change.
Using biased samples leads to false patterns. Only analyzing televised matches creates bias toward big teams and important fixtures. Only analyzing matches you bet on creates selection bias. Only analyzing winning bets creates survivorship bias. For valid statistical analysis, include all relevant matches, not just convenient or memorable ones.
Advanced Statistical Concepts for Football Analysis
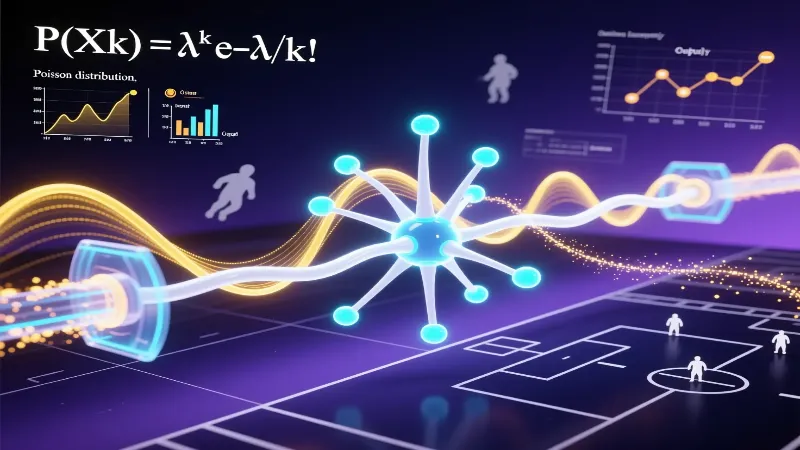
Expected threat (xT) models go beyond expected goals by valuing all possession, not just shots. Every action that moves ball toward more dangerous area increases xT. Pass from midfield into penalty area might add 0.05 xT. This captures buildup play value that xG misses. Teams that consistently generate high xT eventually create high xG, making xT useful leading indicator.
Tracking player movement data reveals patterns invisible in traditional statistics. Distance covered, sprint counts, pressing triggers, defensive positioning---these metrics from tracking data provide insights into fitness, tactics, and match dynamics. Team covering less distance might be tired or might be efficiently controlling space. Context determines interpretation.
Network analysis of passing patterns identifies key players and tactical structures. Which players connect most frequently? Who are the hubs of possession? How does team build attacks? This reveals tactical strengths and weaknesses that simple pass counts miss. If team relies heavily on one playmaker, marking him tightly might disrupt entire attack.
Bayesian updating combines prior beliefs with new evidence optimally. Start with prior assumption about team quality based on historical data. Update that belief as new match data arrives, weighting recent information appropriately without overreacting. This mathematical framework prevents both recency bias and anchoring to outdated information.
Poisson models for goal prediction use statistical distributions to estimate match outcomes. Goals roughly follow Poisson distribution---random events occurring at constant average rate. Input team's attacking and defensive strengths, calculate probability of each scoreline, derive match odds. These models form backbone of many professional betting operations.
Machine learning applications in football betting go beyond traditional statistics. Neural networks can identify complex patterns humans miss. Random forests can combine hundreds of variables effectively. Gradient boosting can optimize predictions iteratively. But beware---complex models often overfit without careful validation.
Game state effects change team behavior significantly. Team leading 1-0 plays differently than team trailing 1-0. Statistics need adjustment for game state. Team might have poor possession stats because they score early then defend. Another team might have inflated attacking stats because they're always chasing games. Raw statistics without game state context mislead.
Regression to the mean is statistical gravity---extreme performances tend toward average over time. Team scoring four goals per game won't maintain that rate. Team conceding zero goals will eventually concede. The question isn't whether regression occurs but when and how much. Betting opportunities arise when markets don't price regression appropriately.
Understanding statistical significance versus practical significance prevents overconfidence. Correlation might be statistically significant with p-value less than 0.05, but effect size might be tiny and practically useless. Focus on effect sizes and confidence intervals, not just significance tests. Big sample sizes make tiny effects statistically significant even when they're meaningless for betting.
Interaction effects between variables complicate analysis. Maybe pressing intensity predicts goals, but only for teams with fast attackers who can exploit high turnovers. Maybe possession predicts winning, but only against weaker teams. Single-variable analysis misses these interactions. Look for conditional relationships where variables matter in specific contexts.
Practical Application: Building Your Statistical Betting System
Start with hypothesis before diving into data. What inefficiency might exist? Why would bookmakers misprice it? Having clear hypothesis prevents aimless data mining and reduces false discoveries. Maybe you hypothesize that bookmakers overvalue home advantage in derbies where travel distance is minimal. Now you can test this specifically.
Collect relevant data systematically. For the derby hypothesis, gather historical derby results, odds, and travel distances. Include regular matches for comparison. Track over multiple seasons for adequate sample size. Store in organized format for analysis.
Test hypothesis rigorously with appropriate statistical methods. Calculate whether shortened travel distance actually reduces home advantage. Compare betting returns on away teams in derbies versus regular matches. Use significance tests but focus on effect sizes and practical implications.
Backtest strategy on historical data, but beware of hindsight bias. It's easy to find patterns in historical data that won't continue. Use out-of-sample testing---develop strategy on one dataset, test on another. If strategy works on 2018-2020 data and also on 2021-2023 data, it's more likely robust.
Paper trade before risking real money. Track hypothetical bets for several months. Does strategy perform as expected? Are you identifying value consistently? Can you execute strategy practically? Paper trading reveals implementation challenges without financial risk.
Start small when betting real money. Even well-tested strategies might fail in practice. Market conditions change. Your execution might differ from backtesting. Small initial stakes let you verify strategy works while limiting downside.
Track everything meticulously. Every bet placed, odds taken, reasoning, outcome. Track your predicted probabilities versus bookmaker odds. Monitor whether you're beating closing line. This data becomes invaluable for improving your system.
Regular review and adjustment keeps system relevant. Which leagues are most profitable? Which bet types work best? Is your edge increasing or decreasing? Monthly or quarterly reviews identify what's working and what needs adjustment.
Combine statistical model with qualitative factors. Statistics capture most information but not everything. Motivational factors, tactical matchups, insider information---these matter too. Use statistics as foundation but incorporate other information for final decisions.
The realistic endpoint isn't perfect prediction model that prints money. It's systematic approach that identifies specific inefficiencies where you have edge, executes disciplined betting strategy, and generates small positive return over large sample. Statistical analysis provides the edge, but discipline and proper bankroll management convert that edge into profit.
Avoiding Statistical Pitfalls
P-hacking and data dredging find false patterns through exhaustive search. Test enough hypotheses and you'll find something "significant" by chance. If you test 100 correlations at 95% confidence, you expect 5 false positives. Cherry-picking the significant ones without mentioning the 95 failures is deceptive.
Protect against this by pre-registering hypotheses, using Bonferroni correction for multiple comparisons, and validating on out-of-sample data. Be suspicious of surprising patterns that lack logical explanation.
Survivorship bias affects historical analysis. We analyze successful teams that survived in top leagues but ignore relegated teams. We study profitable bettors who share their results but not the thousands who lost and quit. This creates skewed picture of what's normal or achievable.
Include failed cases in your analysis. Study relegated teams to understand failure patterns. Acknowledge that profitable betting is exception, not norm. This gives realistic perspective on difficulty and requirements for success.
Confounding variables create spurious correlations. Ice cream sales correlate with drowning deaths---not because ice cream causes drowning but because both increase in summer. In football, correlations might exist because of hidden third variable you haven't considered.
Think critically about why correlation might exist. Is there logical causal mechanism? Could third variable explain the relationship? Test whether correlation holds when controlling for potential confounds.
Overfitting to historical data creates models that fail forward-testing. Model with 50 parameters might perfectly explain last season but fail miserably next season because it captured noise, not signal. Simpler models with fewer parameters often generalize better.
Use regularization techniques, cross-validation, and hold-out samples. Prefer simple models unless complex models show clear improvement in out-of-sample testing. Remember that bookmaker models are incredibly sophisticated---your edge likely comes from specific angles, not general superiority.
Base rate neglect ignores prior probabilities. Penalty is scored 75% of the time. Player has scored 90% of his penalties. Seems like great bet, right? But if match only has 20% chance of producing penalty, the actual probability of player scoring penalty is 0.20 × 0.90 = 18%, making it terrible bet at short odds.
Always consider base rates and conditional probabilities. Event might be likely if it occurs, but unlikely to occur at all. Proper probability calculation multiplies conditional probabilities appropriately.
Simpson's paradox shows how aggregated data can reverse when separated. Team A might have better overall statistics than Team B. But Team B might have better statistics at home and away separately. This happens when Team A plays more home matches. Always disaggregate data appropriately for analysis.
Statistical Tools and Software
Excel or Google Sheets handles basic analysis adequately. Calculate averages, correlations, basic regressions. Create charts for visualization. Build simple models with formulas. For many bettors, spreadsheets provide sufficient analytical power without requiring programming knowledge.
Python with pandas, numpy, and scikit-learn enables advanced analysis. Automate data collection with web scraping. Clean and manipulate large datasets efficiently. Build sophisticated machine learning models. Python has become industry standard for data science and sports analytics.
R programming language excels at statistical analysis. Extensive statistical libraries, excellent visualization with ggplot2, specialized sports analytics packages. R might be better than Python for pure statistical work, though Python is more versatile overall.
SQL databases manage large datasets efficiently. Store years of historical data, query specific subsets quickly, maintain data integrity. PostgreSQL or MySQL work well for betting databases. Combine with Python or R for analysis.
Visualization tools make patterns obvious. Tableau, Power BI, or even Excel charts reveal trends that tables of numbers hide. Plot xG over time, visualize home/away splits, compare team profiles. Good visualization often generates insights that statistical tests miss.
Version control with Git tracks model changes and prevents data loss. As you modify models and analysis code, version control maintains history and enables reverting to previous versions. GitHub provides free hosting for code repositories.
Cloud computing handles intensive calculations. Train complex models on AWS, Google Cloud, or Azure without expensive local hardware. Pay only for computation time used. Essential for deep learning or large-scale simulations.
Automated alerting systems notify you of betting opportunities. Script that checks odds against your model predictions, sends alert when value appears. Reduces manual monitoring and ensures you don't miss time-sensitive opportunities.
The tool choice depends on your technical skills, budget, and ambitions. Start simple with spreadsheets. Add complexity only when current tools limit your analysis. Many profitable bettors use nothing more sophisticated than Excel and disciplined methodology.
Conclusion: Statistical Reality Check
Statistics in football betting are powerful tool but not magic solution. They reveal patterns invisible to casual observation, quantify uncertainties, and identify inefficiencies. But they don't guarantee profit, require significant work to use properly, and must be combined with other skills for success.
Most people using statistics for betting fail because they expect too much from numbers alone. They build complex models without understanding limitations, trust correlations without examining causation, or ignore the massive role of variance in short-term results. Statistics inform better decisions but don't eliminate risk or guarantee outcomes.
The bettors who succeed with statistical approach combine quantitative rigor with qualitative understanding, maintain discipline when models suggest value, adapt when evidence shows models aren't working, and accept that even perfect analysis produces losers through variance.
If you're serious about statistical betting, commit to continuous learning. Football analytics evolve rapidly. New metrics emerge. Markets become more efficient. What works today might not work tomorrow. The edge comes not from finding one statistical secret but from consistently analyzing better than average bettor.
Start with basics---understand xG, track your bets, analyze what works. Build sophistication gradually as you master fundamentals. Don't jump straight to machine learning models without understanding basic probability. Don't expect immediate profit from statistical analysis. The learning curve is steep and variance is cruel.
But for those willing to put in work, statistical analysis offers sustainable edge in football betting. Not get-rich-quick edge, but steady small advantage that compounds over time. In a world where most bettors rely on gut feeling and media narratives, rigorous statistical analysis provides genuine competitive advantage. Use it wisely, combine it with other skills, execute with discipline, and statistics can transform you from recreational punter to profitable bettor.
The numbers don't lie, but they don't tell the whole truth either. Learn to read what statistics reveal and what they conceal. That balanced approach, maintained over hundreds or thousands of bets, is how statistical analysis becomes profitable reality rather than theoretical exercise. The data is there. The tools are available. The edge exists. The question is whether you'll do the work required to find and exploit it.
Return to the Coventry-Bet hub.
